Emotion Recognition based on Multimodal Graph Representation Learning of Senior Utterance
Poster presentation
Best Poster Award
Research approach
Collected 1,512 utterances spanning seven emotions from 24 participants aged 66 to 81. Fused speech and text similarity graphs with SNF, classified them with a GCN and assessed transcription errors.
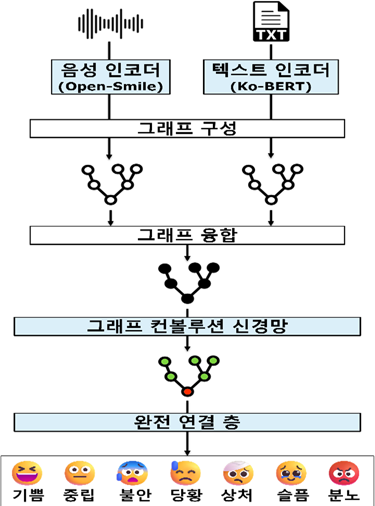
View full-size figure
Results
Subject-independent four-fold evaluation: weighted F1 was 92.33% for speech with original text and 81.38% for speech with transcribed text. Adding speech did not recover the loss from transcription errors under this protocol.
| Input | Weighted F1 |
|---|---|
| Original text | 92.33 |
| Speech + original text | 92.33 |
| Transcribed text | 81.64 |
| Speech + transcribed text | 81.38 |