Multiscale 1D Convolution-Transformer Model for Imagined Speech Decoding
Oral presentation
Research approach
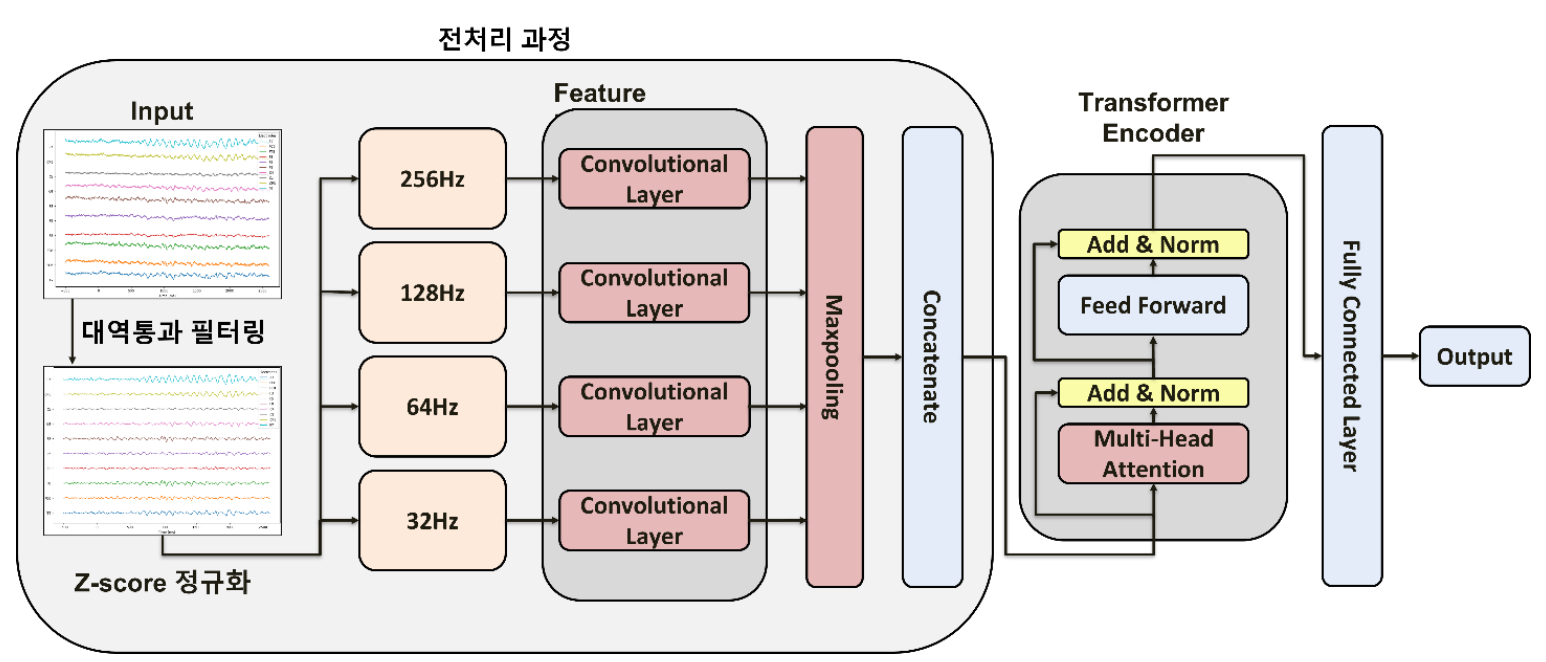
Resampled EEG at 32, 64, 128 and 256 Hz and extracted 1D CNN features at each temporal scale. A Transformer combines these features to decode imagined words.
View full-size figure
Results
Subject-dependent evaluation on BCI Competition 2020 Track 3: 15 participants and five words. Two convolutional layers achieved 73.34 ± 3.26% accuracy, compared with 58.89 ± 7.40% for the Transformer alone.
| Model | Accuracy |
|---|---|
| Transformer | 58.89 ± 7.40 |
| 1-layer 1D CNN + Transformer | 66.00 ± 6.35 |
| 2-layer 1D CNN + Transformer | 73.34 ± 3.26 |
| 3-layer 1D CNN + Transformer | 71.11 ± 4.29 |