Inter-Dialog Contrastive Learning for Multimodal Emotion Recognition in Conversations
Oral presentation
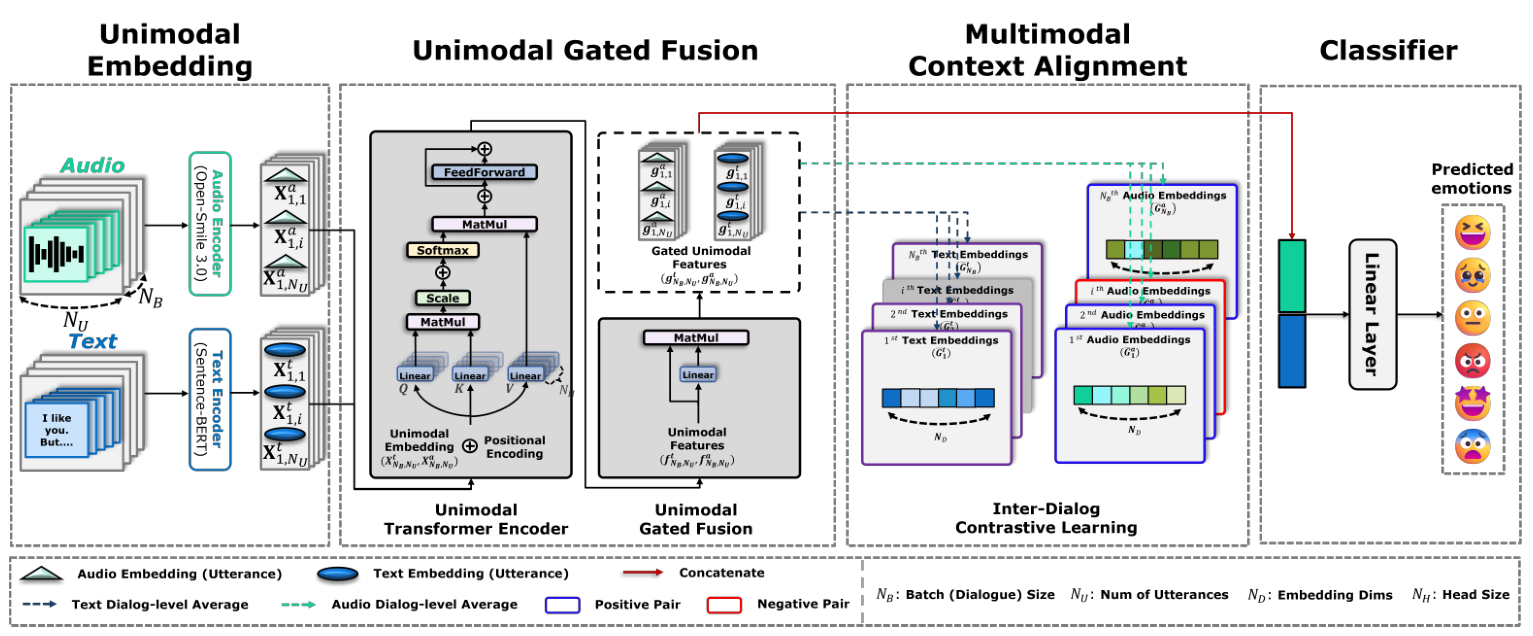
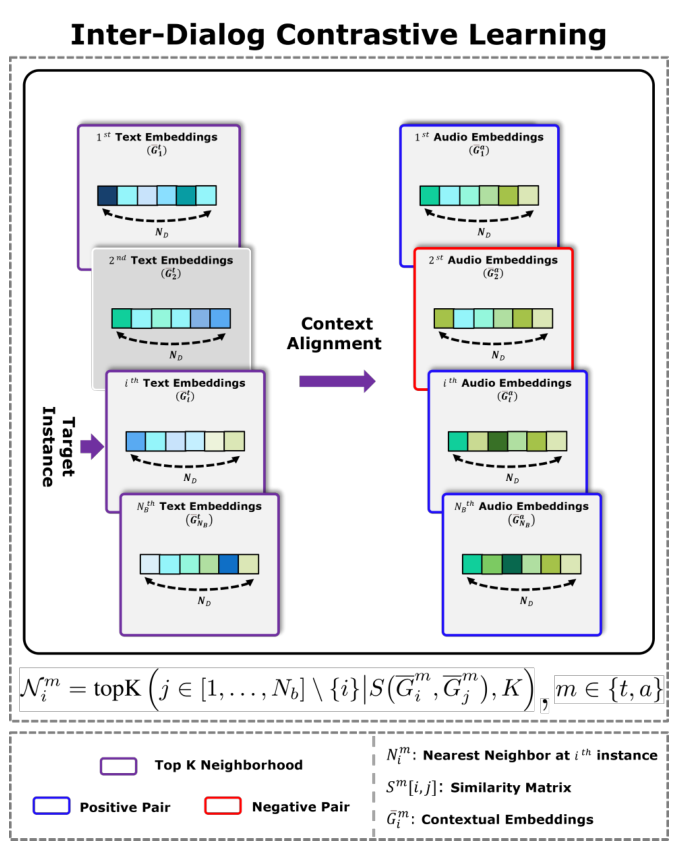
Research approach
Selected neighboring representations across dialogues as positive pairs for audio-text contrastive alignment.
View full-size figure
View full-size figure
Results
With MELD pretraining, IEMOCAP weighted F1 is 85.8% for four classes and 66.6% for six classes.
All publications