Graph-based Modality Alignment for Robustness in Conversational Emotion Recognition
Poster presentation
Research approach
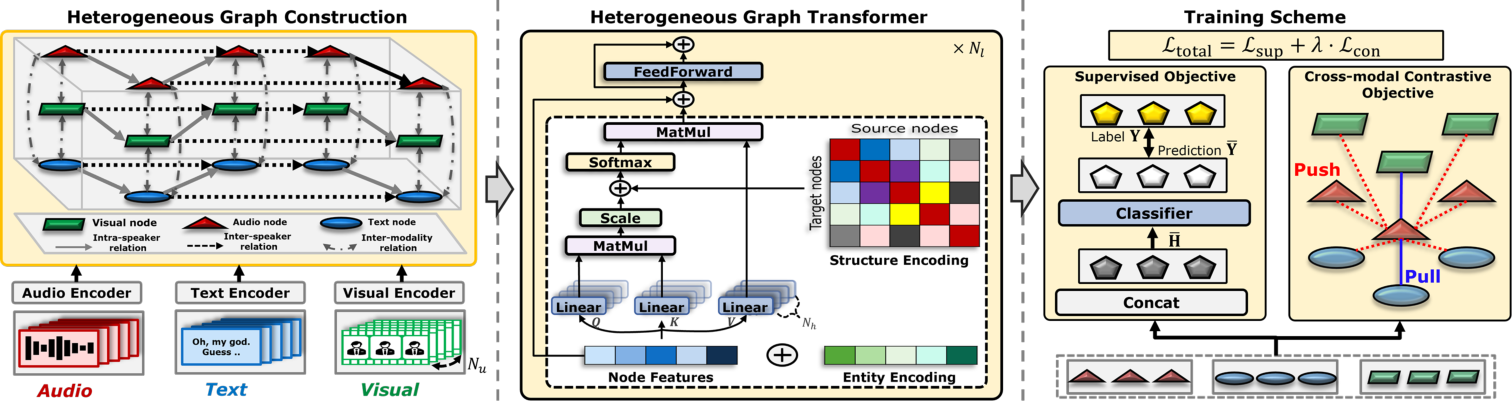
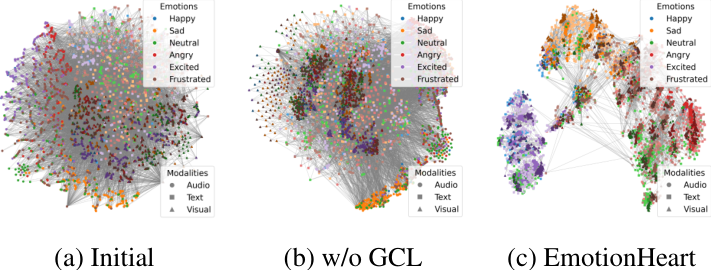
Encoded speaker and modality relationships in a heterogeneous graph and aligned modalities for conversational emotion recognition.
View full-size figure
View full-size figure
Results
Weighted F1: 73.13% on IEMOCAP and 68.99% on MELD. Audio-only IEMOCAP reaches 60.26%; full-input and missing-modality comparisons use different baselines.
| Evaluation setting | Baseline | Proposed model |
|---|---|---|
| IEMOCAP, all inputs | 68.99 | 73.13 |
| MELD, all inputs | 66.75 | 68.99 |
| IEMOCAP, audio only | 54.09 | 60.26 |
InterpretationWeighted F1, averaged over 10 random splits. The full-input baseline is Transformer; the audio-only baseline is GRACE. IEMOCAP: 73.13 with all inputs and 60.26 with audio only.
All publications